Research Paper Summarizer
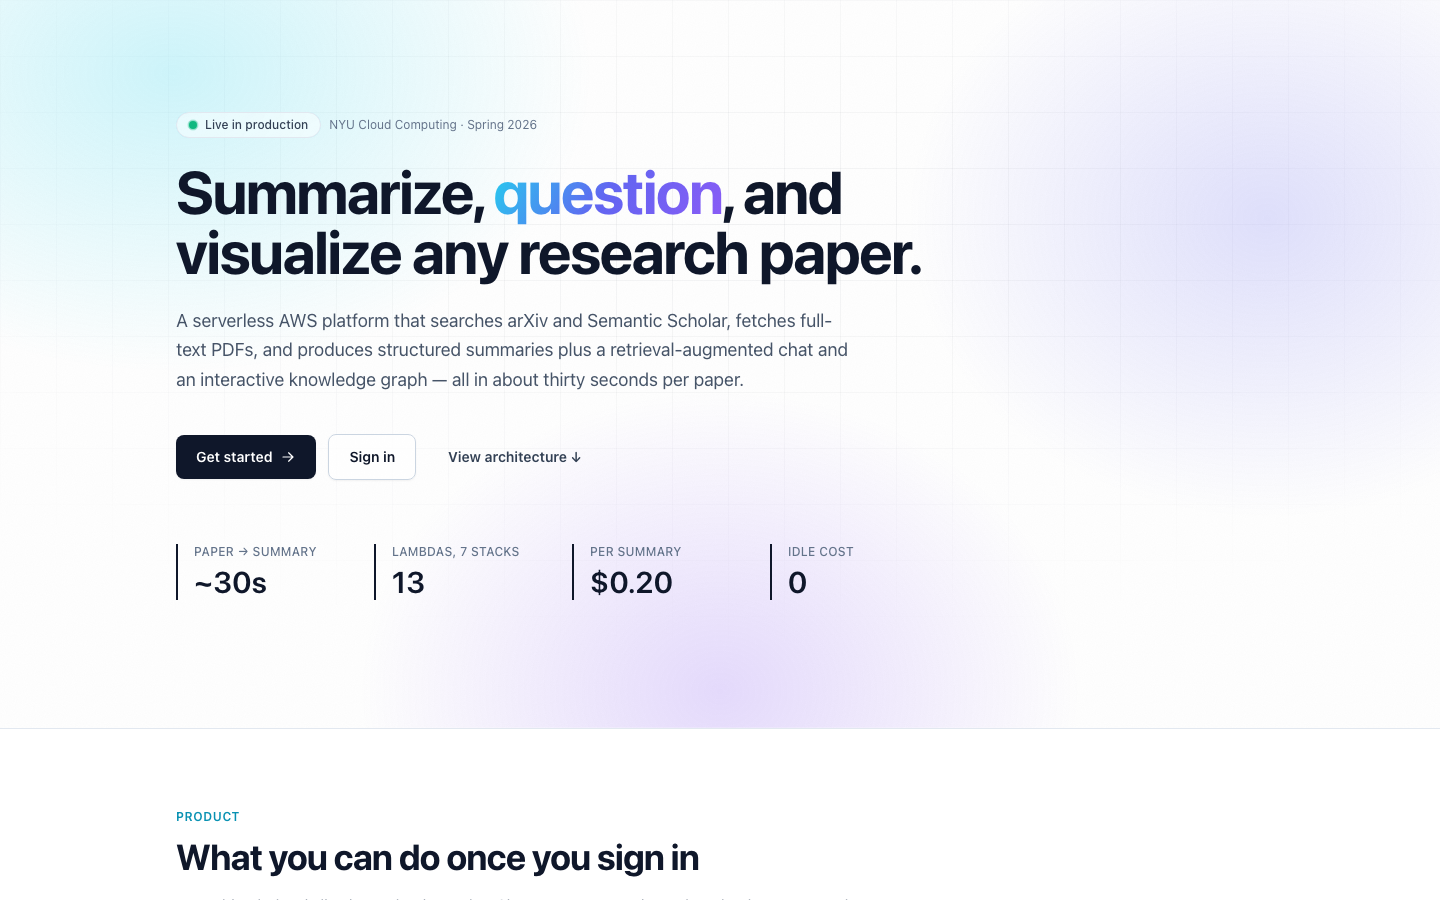
A serverless AWS pipeline that summarizes an arXiv paper in about 30 seconds, and costs nothing while idle.
What it does
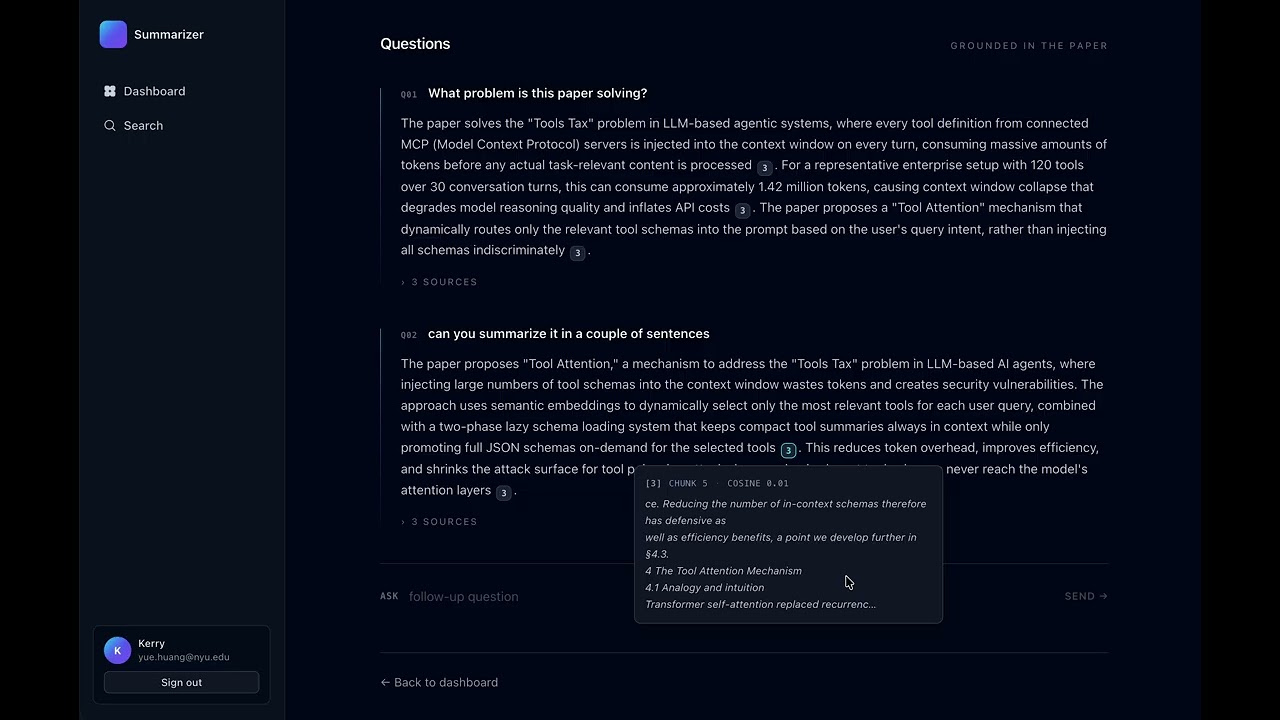
Search arXiv, pick a paper, and get a structured summary, a chat that cites the paper, and a knowledge graph of its concepts. I was the sole architect and primary engineer.
Problems it solves
- Lambda stops at 15 minutes, so a Step Functions map-reduce fans the paper out, capped at five concurrent chunks to respect Bedrock's rate limits.
- Step Functions caps state at 256 KB, so stages pass S3 keys rather than text.
- Two people summarizing the same paper pay once: a SHA-256 content hash in a DynamoDB index returns the cached result.
- Queue redeliveries cannot run a job twice, because the execution name is the job ID.
- A quota that reserves before it spends and refunds on failure, so a burst of requests cannot overrun the budget.
- Different models for different jobs on Bedrock: a large open model for the high-volume summaries, Claude for chat and graph extraction.